HIGH SALIENCE / GUIDES / AI CRAWLERS
GUIDE · SEPTEMBER 26, 2026
AI Crawlers: What GPTBot, OAI-SearchBot and ClaudeBot Do
AI companies run different crawlers, such as GPTBot, OAI-SearchBot, ClaudeBot and PerplexityBot, for different jobs: some fetch pages for AI search answers, some collect training data, and some fetch a page only when a user asks. Blocking the wrong one can quietly remove you from AI answers, while blocking the right one changes nothing about your visibility. This guide lists the main crawlers, what each does according to its operator's own documentation, and a robots.txt setup that keeps you visible in AI search while you decide separately about training.
BY BIKE HAWLEY, FOUNDER · PUBLISHED · UPDATED

01Definition
What is an AI crawler?
An AI crawler is a bot that an AI company such as OpenAI, Anthropic, Perplexity or Google runs to fetch web pages, whether to train its models, to supply its AI search answers, or to load a page when a user asks for it. Each goes by a user agent name, such as GPTBot or PerplexityBot, which is what a robots.txt rule addresses.
Purpose is what matters for visibility: search crawlers decide whether a site can appear in AI answers, and training crawlers do not. Their operators say both kinds honor robots.txt, while some user-triggered fetchers may not.
02The List
List of AI crawlers: user agents and what each one does
Four companies run the main AI crawlers, and each one documents its user agents and what they do.
| Company | User agent | Purpose | Honors robots.txt | What blocking it does |
|---|---|---|---|---|
| OpenAI | OAI-SearchBot | Search: surfaces sites in ChatGPT search | Yes | Allow if you want to appear in ChatGPT search |
| OpenAI | GPTBot | Model training | Yes | Your choice; blocking does not affect ChatGPT search |
| OpenAI | ChatGPT-User | Fetches a page when a user asks | May not apply | User-initiated, not automatic crawling |
| Anthropic | Claude-SearchBot | Search: improves Claude's search results | Yes | Allow if you want to appear in Claude search answers |
| Anthropic | ClaudeBot | Model training | Yes | Your choice |
| Anthropic | Claude-User | Fetches a page when a user asks | Yes | Blocking can reduce visibility in user-directed answers |
| Perplexity | PerplexityBot | Search: surfaces and links sites in Perplexity | Yes | Allow if you want to appear in Perplexity; not used for model training |
| Perplexity | Perplexity-User | Fetches a page when a user asks | Generally no | Treated as a user request |
| Googlebot | Search, including AI Overviews and AI Mode | Yes | Blocking it removes you from Google Search | |
| Google-Extended | robots.txt token for Gemini model training | Yes (token only) | No effect on Google Search inclusion or ranking |
Sources: OpenAI, Anthropic, Perplexity and Google crawler documentation, checked September 2026.
03The Key Split
AI search crawlers vs training crawlers
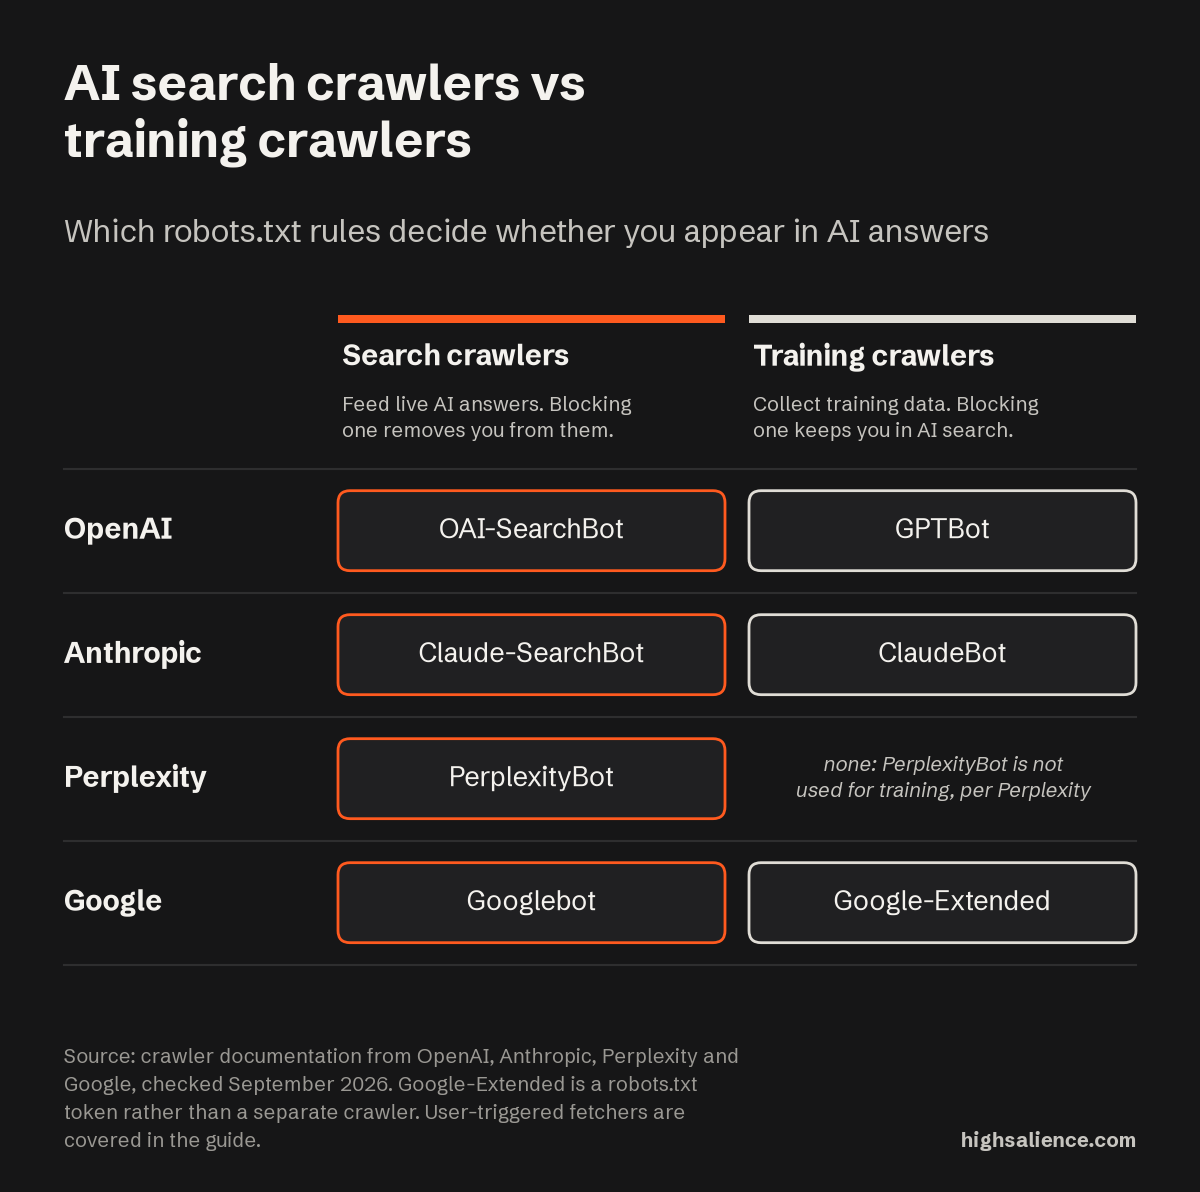
The most important distinction is between AI search crawlers, which feed live answers, and training crawlers, which collect training data. OpenAI states that GPTBot is for training and that blocking it does not affect ChatGPT search, which relies on OAI-SearchBot. Google says Google-Extended controls whether content is used to train Gemini models and does not affect inclusion or ranking in Google Search. Perplexity says PerplexityBot is for search and is not used to train foundation models.
So a company can block every training crawler and still appear in AI search answers, as long as the search crawlers are allowed. The reverse mistake is more common: a blanket block on "AI bots" that takes out OAI-SearchBot or PerplexityBot along with the training crawlers, and removes the site from those answers.
04Setup
How to allow or block AI crawlers in robots.txt
As a starting point, this robots.txt example allows the AI search crawlers and blocks the training crawlers. Swap the training rules to Allow if you are comfortable with your content being used for training. Googlebot is covered by the catch-all rule at the end.
# Search and answer crawlers: allow
User-agent: OAI-SearchBot
Allow: /

User-agent: Claude-SearchBot
Allow: /

User-agent: PerplexityBot
Allow: /

# Training crawlers: your decision (shown blocked here)
User-agent: GPTBot
Disallow: /

User-agent: ClaudeBot
Disallow: /

User-agent: Google-Extended
Disallow: /

# Everyone else
User-agent: *
Allow: /
Two checks after any change: confirm the file returns cleanly at /robots.txt, and confirm your CDN or firewall is not blocking the same bots at the network level. Bot protection that rejects unfamiliar crawlers is one of the most common reasons a site never appears in ChatGPT or Perplexity answers.
05Beyond robots.txt
Does crawler access get you cited in AI answers?
Allowing AI crawlers does not by itself get you cited in AI answers, because access makes you eligible, not visible. Being cited still depends on whether your pages answer the questions being asked, and on what other sites say about you. Our guides to AI citations and getting cited by ChatGPT cover what comes next. And an llms.txt file is not a substitute for crawler access; see llms.txt.
Crawler audits are part of the technical foundation in our AI search optimization engagements, because a single misconfigured rule can hide a site from an entire AI surface. The same audit runs in our B2B SaaS SEO engagements, where pricing, docs and comparison pages need to stay open to AI search crawlers.
06FAQs
AI crawler FAQs
These AI crawler FAQs cover what site owners ask before they change a robots.txt rule.
Should I block GPTBot?
The decision to block GPTBot depends on whether you want your content used to train OpenAI's models. Blocking GPTBot does not remove you from ChatGPT search, which uses OAI-SearchBot. Many companies allow the search crawlers and make a separate decision about training crawlers.
Does blocking Google-Extended remove me from AI Overviews?
No, blocking Google-Extended does not remove you from AI Overviews. Google says Google-Extended does not affect inclusion or ranking in Google Search. AI Overviews and AI Mode are part of Search. To leave them, use the Search generative AI setting Search Console added for all sites on August 31, 2026, or snippet controls.
How do I check if AI crawlers can reach my site?
To see whether AI crawlers can reach your site, read your robots.txt for rules naming their user agents, then check your CDN or firewall bot settings, which can block crawlers even when robots.txt allows them. Server logs will show whether the bots are actually arriving.
Do AI crawlers read llms.txt?
AI crawlers rarely read llms.txt. In one 12-week server-log study, OpenAI's crawler requested robots.txt 3,990 times and llms.txt 7 times. See our llms.txt guide for the details.
Why do user-triggered fetchers ignore robots.txt?
Some companies treat a fetch requested by a person, such as pasting a link into a chat, as a user action rather than crawling, which is what robots.txt covers. OpenAI and Perplexity say their user-triggered fetchers may not follow robots.txt; Anthropic says all of its bots do.
07Sources
Sources and further reading
08Next Step
See if your brand shows up in the answers AI crawlers feed
To see if your brand shows up in the answers AI crawlers feed, start with the Category Salience Brief, the first step in every High Salience engagement: your commercial questions run across Google and the AI surfaces, competitors side by side, and a ranked list of what to fix first.