HIGH SALIENCE / RESEARCH / DATA WAREHOUSE AND ETL TEARDOWN
TEARDOWN 13 · PUBLISHED SEPTEMBER 26, 2026 · DATASET INCLUDED
100 Questions, Thirteenth Category: Data Warehouse and ETL, Where Snowflake Is Picked in 46 Answers and Mentioned Only as the Destination in 32 More
Thirteenth category, same method: 100 data warehouse and ETL queries, ChatGPT with web search on, every answer coded by two independent AI readers for whether it names, recommends or picks each brand, Google's top ten as a control. Three warehouses lead and are usually picked together: Snowflake in 46 answers, BigQuery in 43, Databricks in 37. Snowflake is also mentioned in 32 answers about pipeline tools, but there it is the example of where the data goes, not a choice. Its own website ranks in Google's top ten for 2 of the 100 questions, yet it is the most-cited domain in the dataset, and the two pages the model cites most are two vendors' pricing pages.
01Method
Same query structure, same coding, one new category.
Queries: 100 data warehouse and ETL tools queries built from the same templates as the earlier teardowns: 30 category, 30 comparison, 20 alternative and 20 recommendation. The full list is in the dataset.
Surface: ChatGPT with web search forced on, logged out, United States, English, via the DataForSEO scraper, one run per query, collected September 26, 2026.
Control: Google's top ten organic results for the same queries in the same window, via the DataForSEO SERP API at depth 20 and truncated to the first ten organic results.
Coding: every answer was coded by two independent AI readers (Claude agents working blind from a written protocol), with a third settling disagreements. They were not people. Each brand named was coded picked (the answer's own verdict: "my pick", "choose X if", a shortlist it tells you to act on, the #1 of its ranking), recommended (assigned to a stated case or fit, such as "best for small teams", without being the answer's verdict), listed (named as an option, no fit given), passing (named but not offered as an option) or anchor (the brand being replaced in an "alternatives" query), against a 55-brand dictionary fixed after collection, before the final coding run (every change is listed in DICTIONARY_CHANGES.md), under codebook v2.0. "Recommended" in the tables includes picked brands. The two readers agreed on 97.0% of brand codes in this teardown (98.2% at the recommended level). Cited URLs were deduplicated to their domain and classed as first-party or third-party. The third reader decided 18 of the 595 brand codes in this teardown. A rules-based first pass (the codebook v1.6 rules) agreed with the final codes on 86.1 percent at the recommended level; only the reader codes are published. The readers also coded eight brand mentions that no dictionary alias matched (named by meaning or only by a web address); those rows are in the dataset.
Collection note: the ChatGPT answers and the Google controls were collected on September 26, 2026 through the DataForSEO standard queue, with raw responses saved exactly as returned; the raw files carry UTC timestamps, early September 27. No task failed and none was re-run. Three answers came back as a single opening sentence and are coded as returned. One dictionary change was made after collection: Microsoft Fabric also matches "Fabric", the short name the model often uses when it picks it; the same alias matches "Talend Data Fabric" in two answers, which the readers coded as not a mention. Ten aliases that are also ordinary words (Snowflake, Athena, Stitch, Census, Fabric and others) match only when capitalized. microsoft.com, amazon.com and apache.org each count as the own site of every dictionary brand they host. The split between warehouse questions and pipeline-tool questions (62 and 36, with two stack questions in neither) is ours, used only to describe the results.
One run per query, so this is a teardown, not the benchmark. Frequencies describe this window only. Absence means not observed in this sample, never zero visibility.
02Findings
Three warehouses picked together, one example destination, and a reading list of price pages.
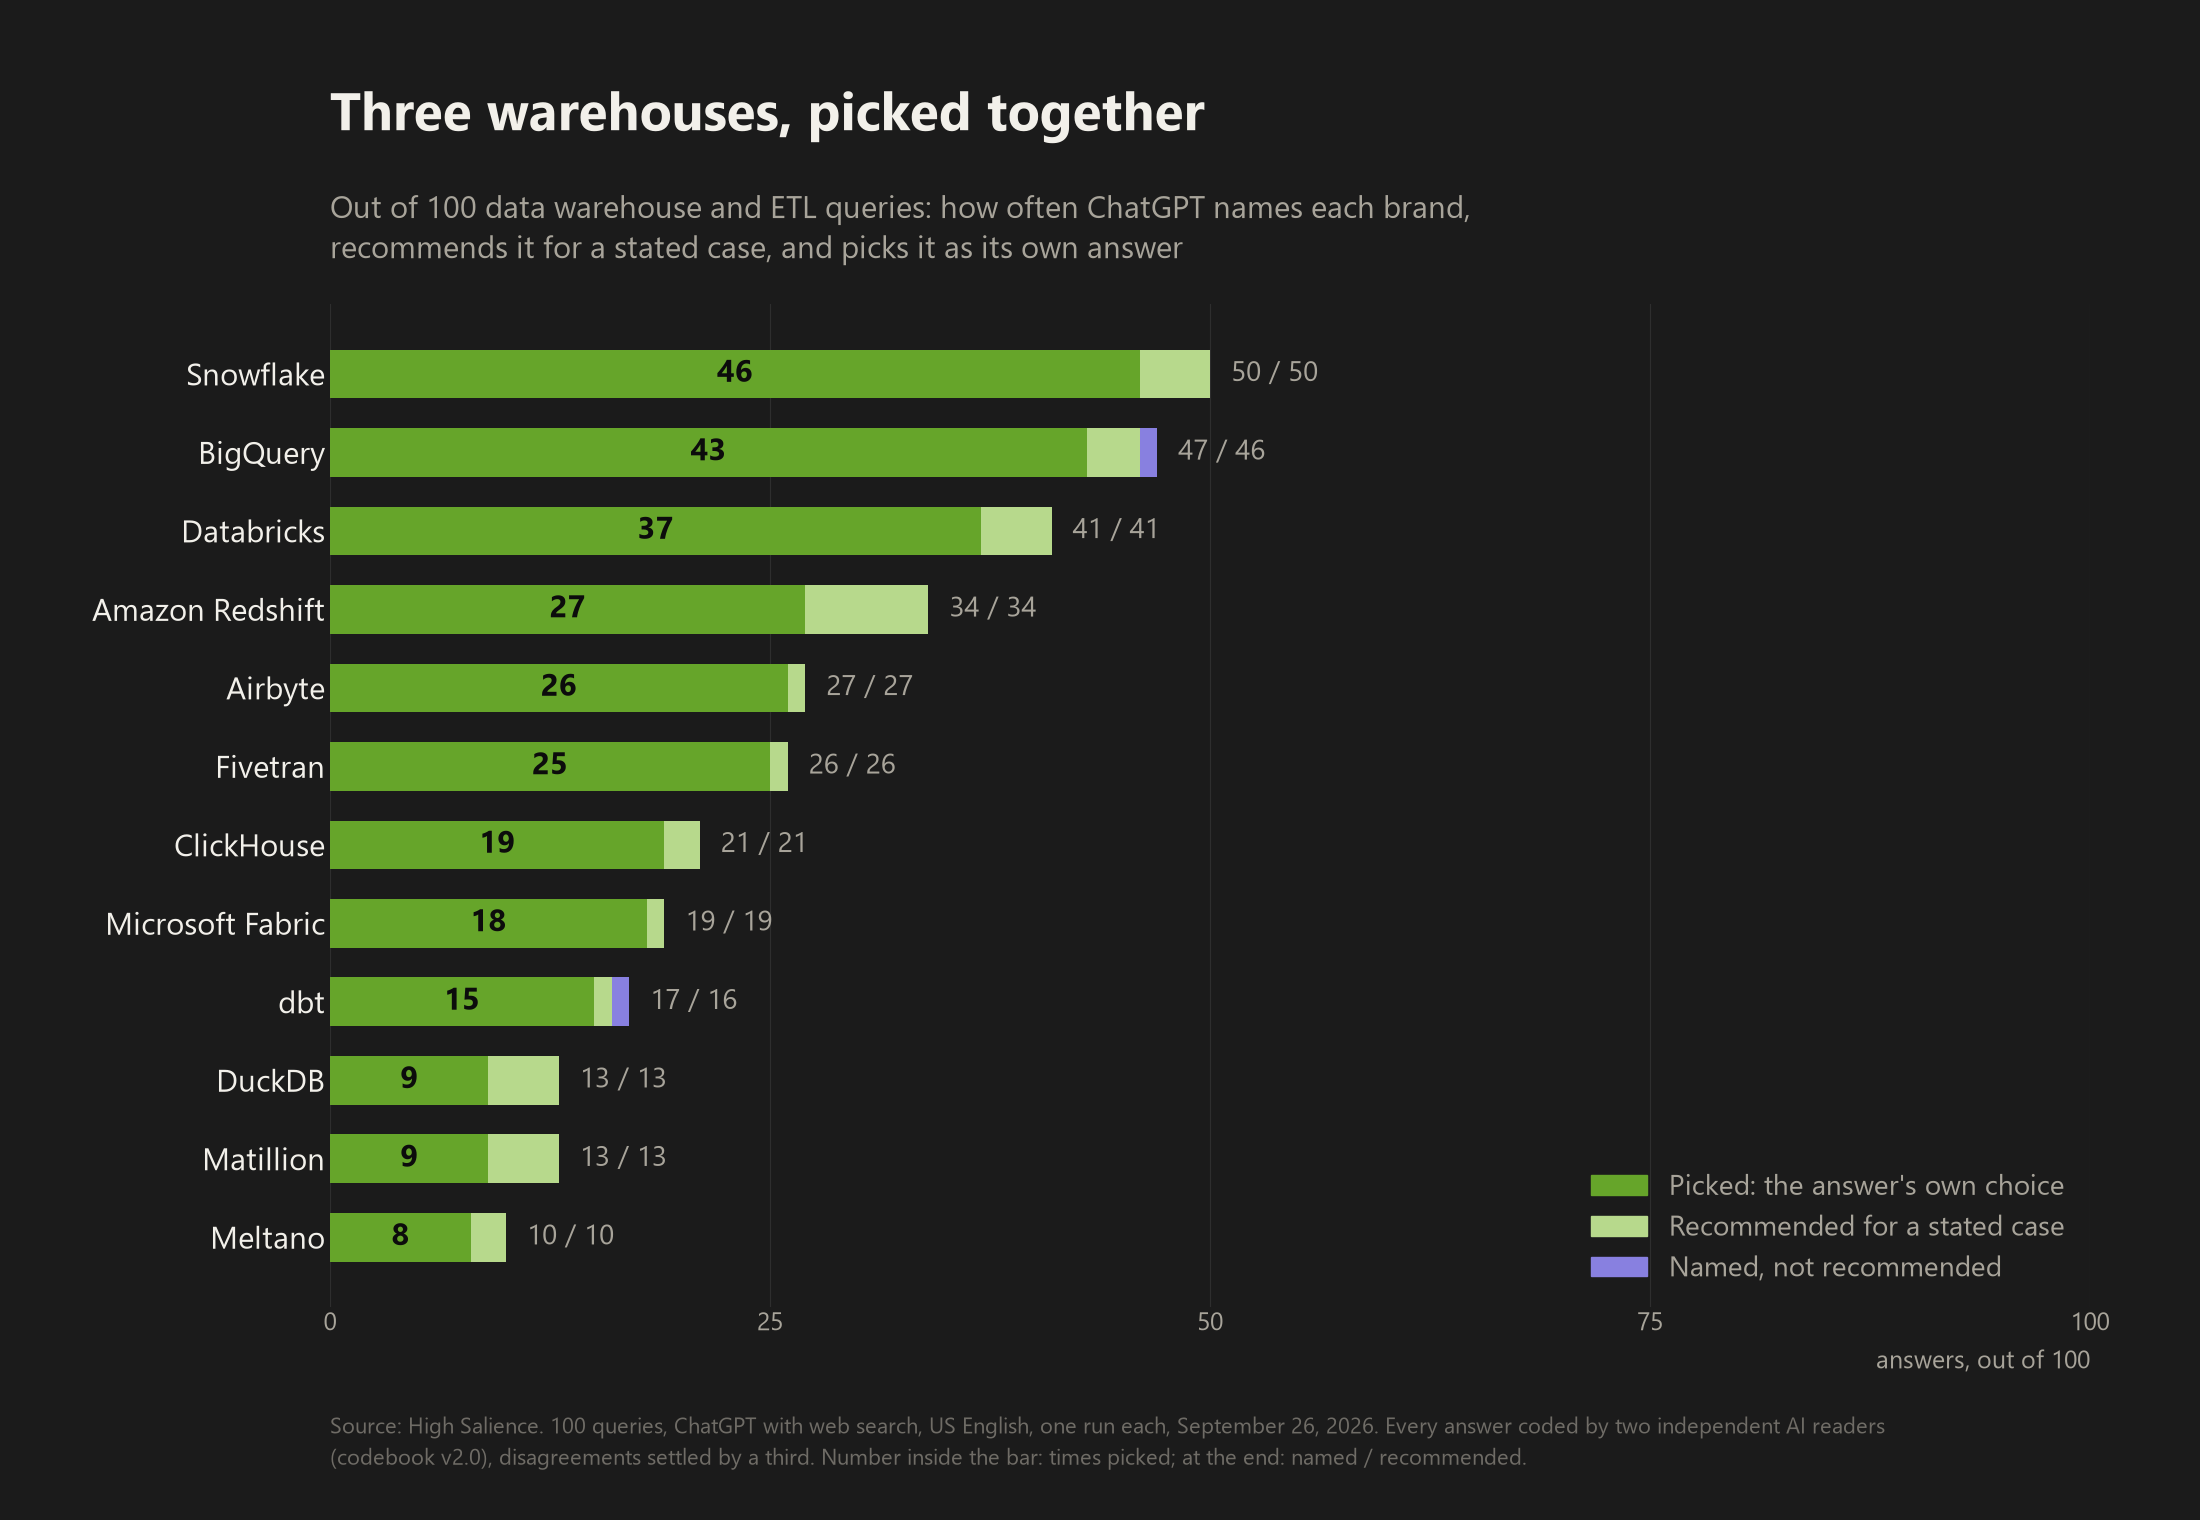
| Brand | Appears in | Recommended in | Picked in | Picked share of appearances |
|---|---|---|---|---|
| Snowflake | 50 | 50 | 46 | 92% |
| BigQuery | 47 | 46 | 43 | 91% |
| Databricks | 41 | 41 | 37 | 90% |
| Amazon Redshift | 34 | 34 | 27 | 79% |
| Airbyte | 27 | 27 | 26 | 96% |
| Fivetran | 26 | 26 | 25 | 96% |
| ClickHouse | 21 | 21 | 19 | 90% |
| Microsoft Fabric | 19 | 19 | 18 | 95% |
| dbt | 17 | 16 | 15 | 88% |
| DuckDB | 13 | 13 | 9 | 69% |
| Matillion | 13 | 13 | 9 | 69% |
| Meltano | 10 | 10 | 8 | 80% |
Each linked brand has its own page: how ChatGPT recommends every brand in this dataset, with positioning labels, head-to-head results and sources.
Out of 100 answers, codebook v2.0. "Picked" means the answer itself chose the brand as its verdict, overall or for a case. "Recommended" means the answer assigned the brand to a stated case or fit, and includes picked brands. "Appears" adds brands named as an option with no fit. The brand being replaced in an "alternatives" query is excluded from all columns.
Three warehouses, picked together
Snowflake is named as an option in 50 of 100 answers, recommended in 50 and picked as the answer's own choice in 46. BigQuery is 47, 46 and 43, Databricks 41, 41 and 37, Amazon Redshift 34, 34 and 27. No brand is named in more than half the answers, the first category in the series so far where that is true, because the question set covers two kinds of product. In the 62 warehouse questions Snowflake is named in 48 and picked in 44, BigQuery 45 and 41, Databricks 40 and 36. The 15 advice questions that ask which warehouse to use picked Snowflake in all 15, BigQuery and Databricks in 14 each, and all three together in 13. Snowflake and BigQuery are picked in the same answer 34 times. Nearly every answer makes a choice: 97 of 100 pick at least one brand, all 20 advice questions produce a pick, and 28 of 30 head-to-heads pick every brand named in the question. Of the 431 times a brand is offered as an option, 426 come with a stated case. Redshift has the widest gap between recommended and picked, 7 answers, each a table or catalog line that files it under AWS-centric companies without making it the answer.
In pipeline answers, Snowflake is the destination, not the pick
Thirty-six of the questions are about pipeline tools: ETL, ELT, data integration, orchestration. Only one of them names Snowflake, yet Snowflake is mentioned in 33 of the 36 answers. In 32 of those it is not offered as an option. It is where the data goes: the example inside a question back to the buyer ("If you tell me your source systems + destination (e.g. Salesforce → Snowflake ...)"), the warehouse a tool loads into, or the warehouse the buyer already has. In 12 answers a question back to the buyer is the only place it appears. When a pipeline answer mentions any of the four big warehouses, Snowflake comes first in 30 of 34. BigQuery plays the same part less often (22 mentions in passing, all in pipeline answers), and so does PostgreSQL, mentioned in 32 answers and named as an option in 7, usually as the example source ("Postgres → Snowflake"). None of these count as recommendations. Snowflake's lead comes from the warehouse questions.
Two pipeline tools, level
Airbyte is named in 27 answers and picked in 26; Fivetran is named in 26 and picked in 25. Across the 36 pipeline questions Airbyte is picked in 22, Fivetran in 21, and both in the same answer in 14. The four advice questions that ask which ETL tool to use picked Airbyte in all four, Fivetran and dbt in three each. Matillion (13 named, 9 picked) and Meltano (10 and 8) follow. dbt is mentioned in 36 answers but named as an option in only 17: in 19 it is the transformation step in an example stack or a tool the buyer already uses. When it is offered, it is picked in 15 of 17.
The challengers: ClickHouse, DuckDB and Fabric
When a question asks for an alternative to one of the big warehouses (cheaper, free, simpler, open source: 11 questions), the model reaches for two open-source engines. ClickHouse is named in all 11 and picked in 10, and DuckDB is named in 10 and picked in 6. Microsoft Fabric is named in 19 answers and picked in 18; in 16 of those 18 the deciding line ties it to Microsoft, Azure or Power BI ("Power BI + Microsoft ecosystem → Fabric").
Ranking is not the route
Of the 365 picks, 303 were for brands whose own website did not rank in Google's top ten for the question, 83 percent. snowflake.com ranked in the top ten for 2 of the 100 questions, and for 1 of the 46 answers that pick Snowflake. It works the other way too: domo.com ranked for 31 of the questions and Domo is named in none of the answers; skyvia.com ranked for 15 and Skyvia is never mentioned. Reddit ranked for 95 of the 100 questions and was cited in none. Google's top ten here is 78 percent third-party pages.
The vendors write the reading list, starting with the price list
Across 100 answers there were 267 citation events to 82 domains. Vendors' own sites took 197 of them, 74 percent, the highest share in the series so far, and 60 answers cited nothing but vendor pages. snowflake.com is the most-cited domain, in 29 answers, 18 of them to questions that never mention Snowflake; Snowflake is picked in 27 of the 29. The two most-cited pages in the dataset are price lists: BigQuery's pricing page and Snowflake's, each cited in 15 answers (16 counting Snowflake's pricing FAQ), and 38 answers cite at least one vendor pricing page. ClickHouse's own comparison and alternatives articles were cited in 10 answers, 8 of them to questions that do not name ClickHouse, and ClickHouse was picked in all 10. Only one citation came from the codebook's review-and-media list (Gartner), the lowest share in the series so far. The most-cited independent sources, InfoWorld (5 answers) and ondelva.com (4), ranked in Google's top ten for none of those questions. Reddit and Wikipedia have zero citations.
Fifty-four of the 267 citation events involved a domain that also sat in Google's top ten for that query, 20 percent.
0313 categories, side by side
Same rulebook, every category so far.
| Measure (codebook v2.0) | Project management, Sept 8 | CRM, Sept 17 | Email marketing, Sept 17 | Help desk, Sept 17 | Accounting, Sept 17 | Payment processing, Sept 17 | Payroll, Sept 21 | HR software, Sept 26 | Applicant tracking, Sept 26 | Password managers, Sept 26 | Endpoint security, Sept 26 | Business intelligence, Sept 26 | Data warehouse and ETL, Sept 26 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Recommendations per category answer (average) | 5.9 | 4.3 | 5.0 | 5.5 | 4.3 | 4.2 | 4.6 | 5.0 | 4.5 | 3.4 | 4.7 | 5.0 | 4.5 |
| Answers with no recommended dictionary brand | 1 of 100 | 5 of 100 | 1 of 100 | 1 of 100 | 0 of 100 | 5 of 100 | 1 of 100 | 6 of 100 | 5 of 100 | 3 of 100 | 3 of 100 | 3 of 100 | 2 of 100 |
| Answers with no pick (the answer's own verdict) | 2 of 100 | 11 of 100 | 2 of 100 | 4 of 100 | 9 of 100 | 22 of 100 | 19 of 100 | 17 of 100 | 12 of 100 | 7 of 100 | 7 of 100 | 5 of 100 | 3 of 100 |
| Most-recommended brand: appears / recommended | Asana 73 / 73 | HubSpot 75 / 74 | Mailchimp 58 / 56 | Zendesk 70 / 69 | QuickBooks 75 / 73 | Stripe 70 / 68 | Gusto 73 / 73 | Rippling 58 / 57 | Workable 53 / 52 | Bitwarden 84 / 82 | Microsoft Defender 68 / 67 | Power BI 75 / 73 | Snowflake 50 / 50 |
| Most-picked brand: appears / picked | Asana 73 / 70 | HubSpot 75 / 69 | Mailchimp 58 / 44 | Zendesk 70 / 61 | QuickBooks 75 / 65 | Stripe 70 / 54 | Gusto 73 / 61 | Rippling 58 / 50 | Workable 53 / 47 | Bitwarden 84 / 78 | Microsoft Defender 68 / 62 | Power BI 75 / 69 | Snowflake 50 / 46 |
| Head-to-head queries recommending every named brand | 30 of 30 | 28 of 30 | 30 of 30 | 29 of 30 | 26 of 30 | 28 of 30 | 30 of 30 | 28 of 30 | 29 of 30 | 28 of 30 | 30 of 30 | 29 of 30 | 28 of 30 |
| Head-to-head queries picking every named brand | 30 of 30 | 23 of 30 | 29 of 30 | 29 of 30 | 25 of 30 | 19 of 30 | 21 of 30 | 21 of 30 | 29 of 30 | 27 of 30 | 29 of 30 | 29 of 30 | 28 of 30 |
| Recommendation-intent queries with a dictionary recommendation | 19 of 20 | 18 of 20 | 20 of 20 | 20 of 20 | 20 of 20 | 19 of 20 | 20 of 20 | 18 of 20 | 20 of 20 | 19 of 20 | 19 of 20 | 20 of 20 | 20 of 20 |
| Recommendation-intent queries with a pick | 19 of 20 | 18 of 20 | 20 of 20 | 20 of 20 | 19 of 20 | 18 of 20 | 20 of 20 | 18 of 20 | 20 of 20 | 19 of 20 | 19 of 20 | 20 of 20 | 20 of 20 |
| Recommended mentions where the brand does not rank in Google's top 10 | 398 of 468 (85%) | 269 of 387 (70%) | 313 of 419 (75%) | 350 of 445 (79%) | 206 of 368 (56%) | 294 of 360 (82%) | 202 of 383 (53%) | 310 of 405 (77%) | 333 of 388 (86%) | 218 of 304 (72%) | 273 of 369 (74%) | 355 of 401 (89%) | 360 of 426 (85%) |
| Picked mentions where the brand does not rank in Google's top 10 | 349 of 416 (84%) | 226 of 330 (68%) | 270 of 370 (73%) | 291 of 380 (77%) | 141 of 279 (51%) | 170 of 222 (77%) | 113 of 246 (46%) | 232 of 311 (75%) | 261 of 311 (84%) | 163 of 241 (68%) | 231 of 319 (72%) | 292 of 336 (87%) | 303 of 365 (83%) |
| Google top 10 that is third-party pages | 746 of 1,000 (75%) | 710 of 1,000 (71%) | 720 of 1,000 (72%) | 714 of 1,000 (71%) | 743 of 1,000 (74%) | 787 of 1,000 (79%) | 653 of 1,000 (65%) | 820 of 1,000 (82%) | 871 of 1,000 (87%) | 866 of 1,000 (87%) | 778 of 1,000 (78%) | 823 of 999 (82%) | 777 of 1,000 (78%) |
| Citation events to vendors' own sites | 216 of 362 (60%) | 136 of 320 (42%) | 193 of 367 (53%) | 152 of 345 (44%) | 125 of 302 (41%) | 161 of 301 (53%) | 192 of 314 (61%) | 167 of 325 (51%) | 139 of 311 (45%) | 201 of 292 (69%) | 149 of 266 (56%) | 190 of 274 (69%) | 197 of 267 (74%) |
| Answers citing only vendor pages | 50 of 100 | 40 of 100 | 37 of 100 | 27 of 100 | 34 of 100 | 47 of 100 | 49 of 100 | 34 of 100 | 30 of 100 | 65 of 100 | 44 of 100 | 60 of 100 | 60 of 100 |
| Share of citations in the 10 most-cited domains | 54% | 40% | 42% | 45% | 55% | 58% | 55% | 46% | 44% | 72% | 58% | 62% | 60% |
| Citation events whose domain is in Google's top 10 | 83 of 362 (23%) | 83 of 320 (26%) | 97 of 367 (26%) | 80 of 345 (23%) | 99 of 302 (33%) | 98 of 301 (33%) | 134 of 314 (43%) | 85 of 325 (26%) | 59 of 311 (19%) | 78 of 292 (27%) | 72 of 266 (27%) | 44 of 274 (16%) | 54 of 267 (20%) |
| Reddit and Wikipedia citations | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
All columns are coded under codebook v2.0 by two independent AI readers per answer; the project management column is the September 8 dataset recoded under it. Each teardown is one run per query in its own window, so differences between columns mix category with collection date.
04What this changes
Four things, in order.
Your pricing page is a primary source. The two most-cited pages in this dataset are BigQuery's and Snowflake's pricing pages, 15 answers each, and 38 of 100 answers cite at least one pricing page. A pricing page that is complete, current and easy to quote is working for you in AI answers.
Being the example is not being the pick. Snowflake is mentioned in 33 of the 36 answers about pipeline tools and offered as an option in one. Its picks come from the warehouse questions, 44 of 62. Count the answers that choose you, not the answers that mention you.
Write the comparison yourself. ClickHouse's own alternatives and comparison articles were cited in 10 answers, 8 of them to questions that do not name ClickHouse, and ClickHouse was picked in all 10.
Google rank is a separate job. snowflake.com ranked for 2 of 100 questions and Snowflake still led the picks. domo.com ranked for 31 and Domo was named in none. Measure both, separately.
05Limitations
What this teardown cannot tell you.
One run per query means answer variance is unmeasured; Benchmark 01 runs each query three times across three surfaces. The teardowns are collected on different days, so differences between categories mix the category with the date. The brand dictionary covers the general data warehouse and ETL tools market and deliberately excludes vertical tools, so their appearances are described in prose and not counted. The readers are AI models, not people: they follow a written protocol and agree with each other closely, but a shared blind spot would not show up as disagreement. The line between picked and recommended is a judgment, documented in the protocol with examples. Sentiment is not coded. No vendor-tool cross-check was read for this category. Google's control counts a brand as ranking only when its own domain is in the top ten; a listicle that features the brand does not count. One run per question, one day, United States, English, logged out. Answers vary between runs, so these are frequencies for this sample. The coding is done by AI readers following a published protocol; the line between a pick and a recommendation for a stated case is a judgment, and 18 codes needed the third reader. Three answers came back as a single sentence, and two of the three answers with no pick are among them. The dictionary gained one alias after collection, disclosed with its side effects. The split into warehouse and pipeline-tool questions is ours. The review-and-media list is the codebook's fixed list, so publishers such as InfoWorld count as other third-party pages here.
06Dataset
Check it, don't believe it.
Every number above can be recomputed from these files. CC BY 4.0: use them, cite the page.
- queries.csv: the 100 queries with intent labels.
- brands.csv: the 55-brand dictionary with aliases and canonical domains.
- mentions.csv: 593 coded brand mentions with position, type, a 0/1 picked column and whether the brand's domain was in Google's top ten.
- citations.csv: 267 citation events with domain class and Google overlap.
- observations.csv: one row per query with brand, recommendation, citation and control counts.
- dictionary-changes.md: the one dictionary change made after collection, with its effect on the counts
- brands-original.csv: the dictionary as drafted before collection
- coder-notes.md: coding method, reader agreement, the judgment calls the third reader decided, and dictionary notes
- codebook.md: the rulebook, with dated amendments through v2.0.
- reader-protocol.md: the written protocol both readers coded against (codebook v2.0).
- picked_stats.json: the picked-level figures.
The earlier teardowns: Teardown 01, project management, Teardown 02, crm, Teardown 03, email marketing, Teardown 04, help desk, Teardown 05, accounting, Teardown 06, payment processing, Teardown 07, payroll, Teardown 08, hr software, Teardown 09, applicant tracking, Teardown 10, password managers, Teardown 11, endpoint security, Teardown 12, business intelligence.
Thirteen categories, and the reading list is still the story.
In data warehouses and ETL the model reads the vendors' pricing pages and one vendor's comparison articles. In password managers it reads the vendors' own sites. In applicant tracking, a comparison library that does not rank. Finding out what the model is reading for your category is the first thing a Category Salience Brief does, with a query set you approve first.