HIGH SALIENCE / RESEARCH / AI WRITING TOOLS TEARDOWN
TEARDOWN 21 · PUBLISHED SEPTEMBER 26, 2026 · DATASET INCLUDED
100 Questions, Twenty-first Category: AI Writing Tools, Where the Model's Own Product Is Picked Most and Specialists Win the Named Uses
Twenty-first category, same method: 100 AI writing tool queries, ChatGPT with web search on, every answer coded by two independent AI readers from a published protocol, Google's top ten as a control. This category has a built-in complication: the system answering the questions is also one of the products being asked about. ChatGPT is named as an option in 58 answers and picked as the answer's own choice in 50, more than any other tool; Jasper (35) and Grammarly (34) come next. In the 15 questions that name a use or a platform, a specialist or the platform's own assistant is picked every time, with ChatGPT beside it in 9. And the model read more widely here than in any earlier teardown: 143 different sites, about half of its citations from third-party pages that are neither vendors nor review publishers.
01Method
Same query structure, same coding, one new category.
Queries: 100 AI writing tools queries built from the same templates as the earlier teardowns: 30 category, 30 comparison, 20 alternative and 20 recommendation. The full list is in the dataset.
Surface: ChatGPT with web search forced on, logged out, United States, English, via the DataForSEO scraper, one run per query, collected September 26, 2026.
Control: Google's top ten organic results for the same queries in the same window, via the DataForSEO SERP API at depth 20 and truncated to the first ten organic results.
Coding: every answer was coded by two independent AI readers (Claude agents working blind from a written protocol), with a third settling disagreements. They were not people. Each brand named was coded picked (the answer's own verdict: "my pick", "choose X if", a shortlist it tells you to act on, the #1 of its ranking), recommended (assigned to a stated case or fit, such as "best for small teams", without being the answer's verdict), listed (named as an option, no fit given), passing (named but not offered as an option) or anchor (the brand being replaced in an "alternatives" query), against a 53-brand dictionary fixed before collection, under codebook v2.0. "Recommended" in the tables includes picked brands. The two readers agreed on 97.3% of brand codes in this teardown (100.0% at the recommended level). Cited URLs were deduplicated to their domain and classed as first-party or third-party. The third reader decided 11 of the 414 brand codes in this teardown. A rules-based first pass (the codebook v1.6 rules) agreed with the final codes on 91.1 percent at the recommended level; only the reader codes are published. The readers also coded eight brand mentions that no dictionary alias matched (named by meaning or only by a web address); those rows are in the dataset.
Collection note: the ChatGPT answers and the Google controls were collected on the evening of September 26, 2026, US Mountain time, through the DataForSEO standard queue, with raw responses saved exactly as returned; the raw files carry UTC timestamps, early September 27. No task failed and none was re-run. Every link ChatGPT cites carries the tag "utm_source=chatgpt.com"; link addresses are removed before coding, so the tag never counts as a mention of ChatGPT. The ChatGPT row also counts mentions of OpenAI and its GPT models; OpenAI models named only as the engine inside another product are coded passing. Fourteen aliases (ordinary words and first names such as Claude, Jasper, Surfer and Lavender) match only when capitalized. The dictionary was not changed after collection; a case-sensitivity change to the ChatGPT aliases was tried and reverted, and DICTIONARY_CHANGES.md records it.
One run per query, so this is a teardown, not the benchmark. Frequencies describe this window only. Absence means not observed in this sample, never zero visibility.
02Findings
The model's own product is picked most, specialists win the named uses, and the widest reading list yet.
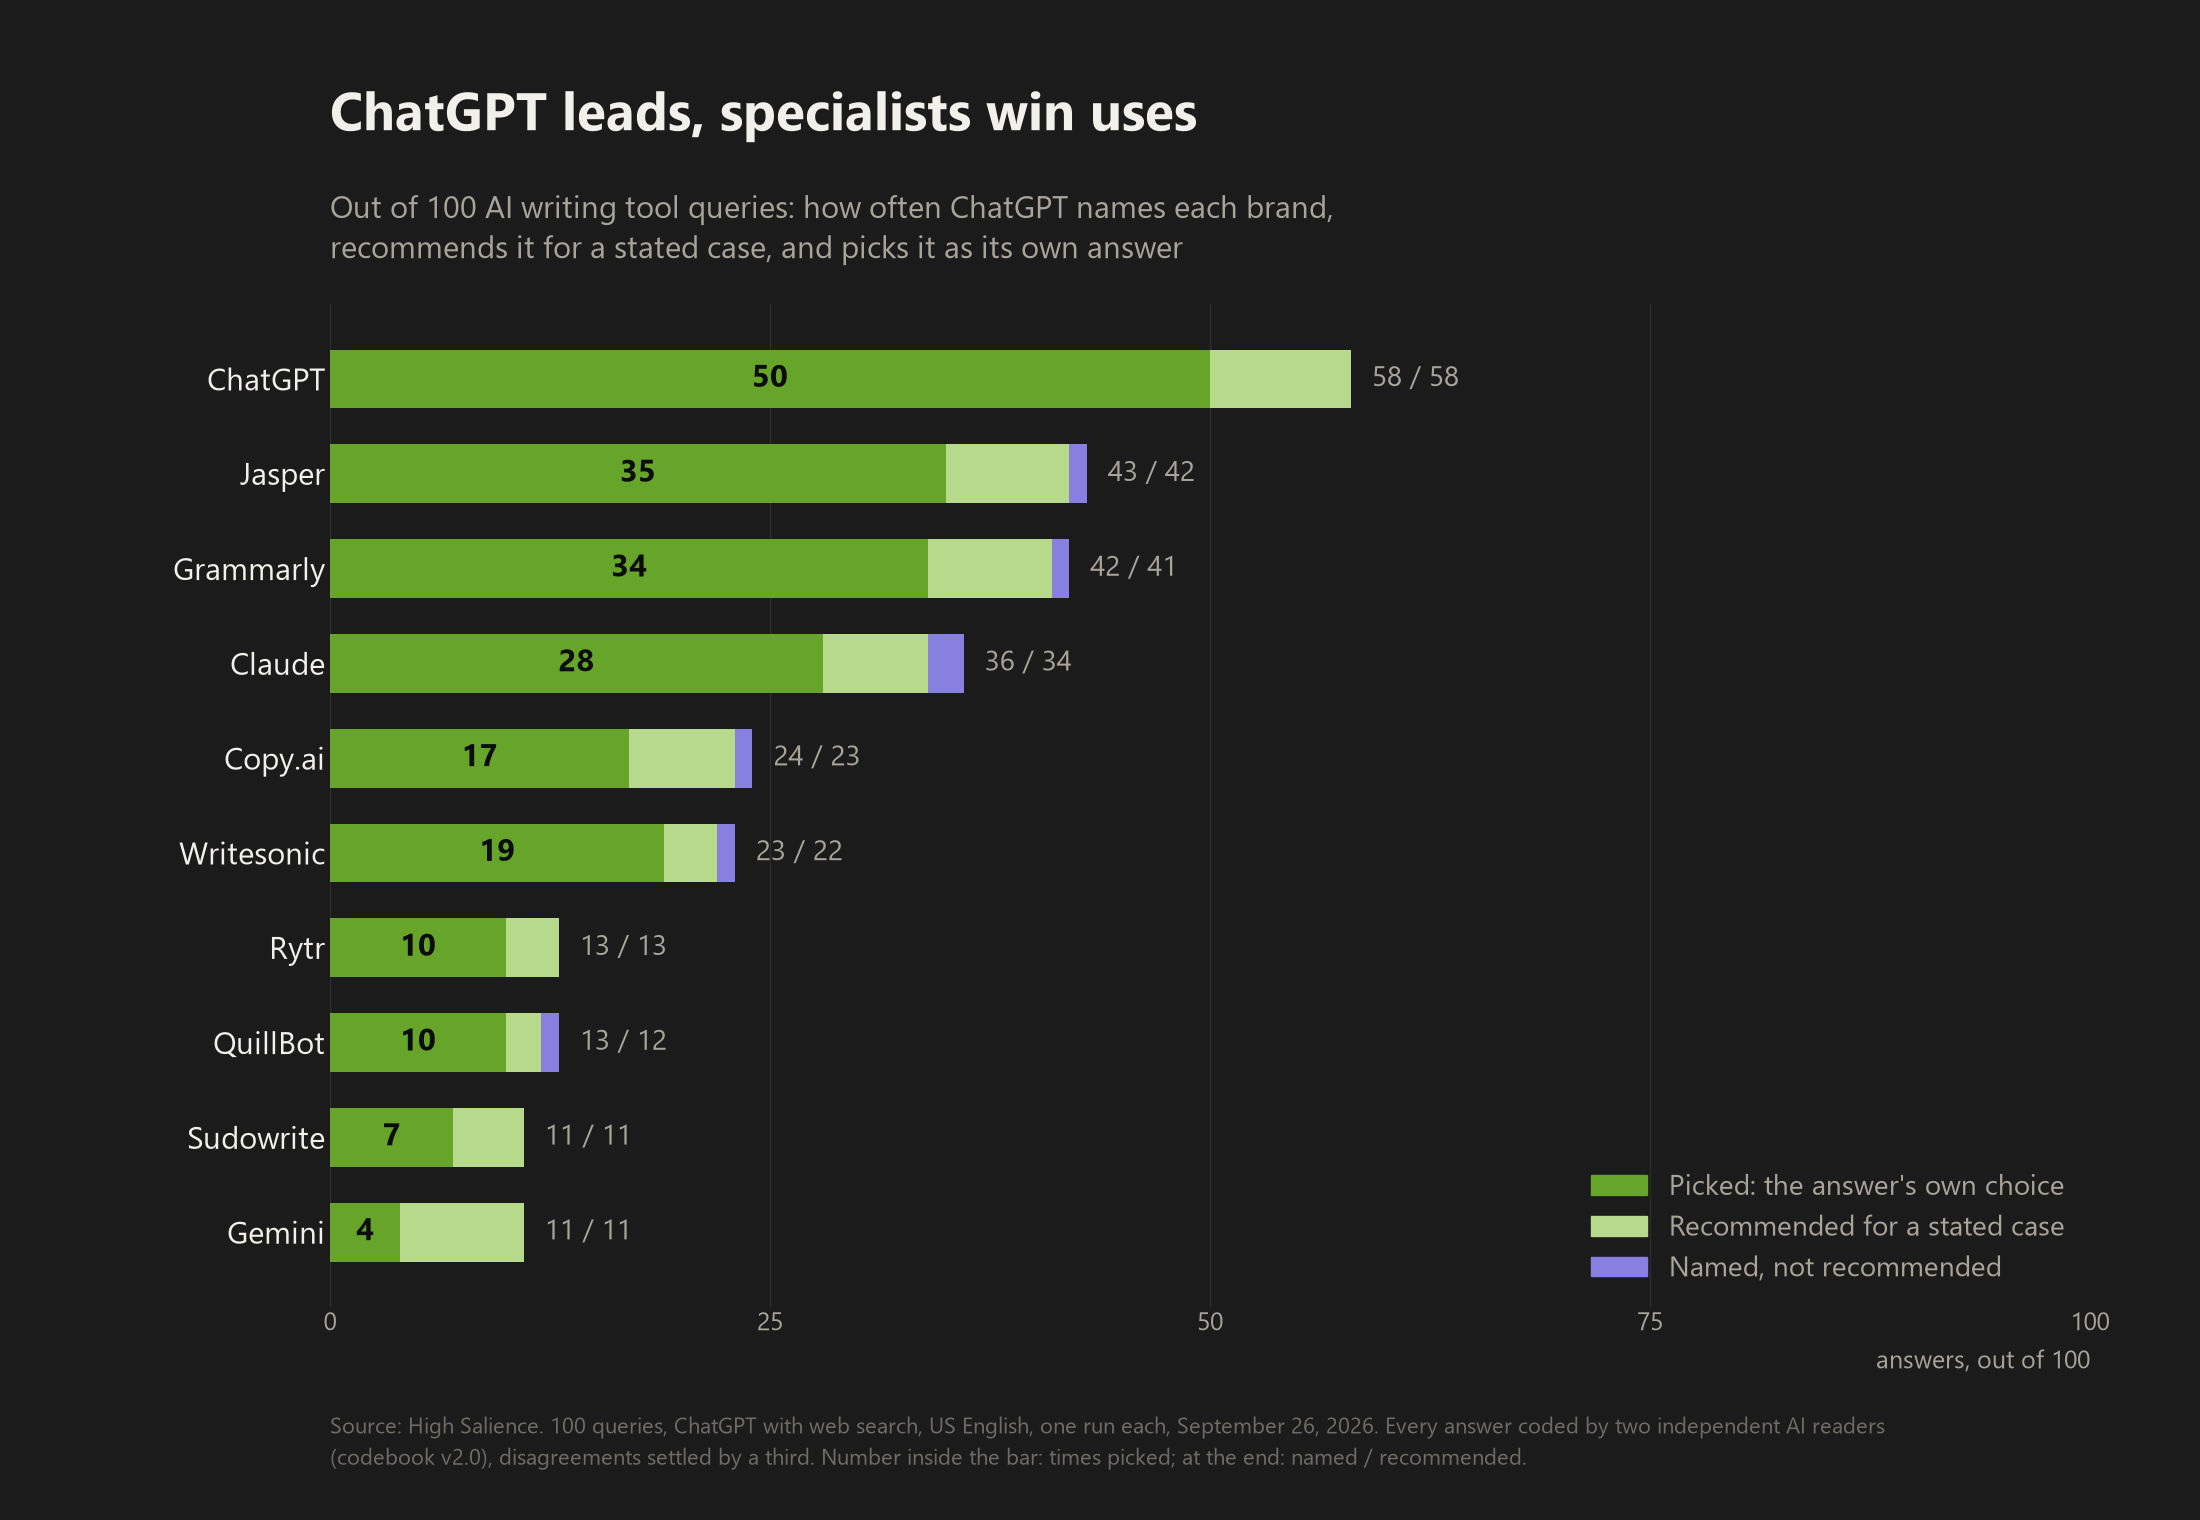
| Brand | Appears in | Recommended in | Picked in | Picked share of appearances |
|---|---|---|---|---|
| ChatGPT | 58 | 58 | 50 | 86% |
| Jasper | 43 | 42 | 35 | 81% |
| Grammarly | 42 | 41 | 34 | 81% |
| Claude | 36 | 34 | 28 | 78% |
| Copy.ai | 24 | 23 | 17 | 71% |
| Writesonic | 23 | 22 | 19 | 83% |
| Rytr | 13 | 13 | 10 | 77% |
| QuillBot | 13 | 12 | 10 | 77% |
| Sudowrite | 11 | 11 | 7 | 64% |
| Gemini | 11 | 11 | 4 | 36% |
Each linked brand has its own page: how ChatGPT recommends every brand in this dataset, with positioning labels, head-to-head results and sources.
Out of 100 answers, codebook v2.0. "Picked" means the answer itself chose the brand as its verdict, overall or for a case. "Recommended" means the answer assigned the brand to a stated case or fit, and includes picked brands. "Appears" adds brands named as an option with no fit. The brand being replaced in an "alternatives" query is excluded from all columns.
ChatGPT leads the general questions
ChatGPT is named as an option in 58 of 100 answers, recommended in all 58 and picked as the answer's own choice in 50. Jasper is named in 43 and picked in 35, Grammarly 42 and 34, Claude 36 and 28. On the seven category questions that name no audience or use (best, best in 2026, free, cheapest, easiest, most popular, top rated), ChatGPT is picked in all seven. All 20 direct advice questions produced a pick: ChatGPT was among the picks in 13, Grammarly in 9, Jasper in 8, Claude in 5. Eight of the 100 questions name ChatGPT; in the other 92 it is named in 52 answers and picked in 45. It is rarely the only choice: in 47 of its 50 picks the answer picks another tool too.
Read that with the obvious caveat
ChatGPT is the system answering these questions, and these data cannot say whether its lead reflects the category or a preference for its own product. They can show what sits around it. ChatGPT's own site ranked in Google's top ten for none of the 100 questions. openai.com or chatgpt.com is cited in 15 answers, and ChatGPT is picked in 13 of them. No answer names ChatGPT as the system giving the answer. In nine more answers ChatGPT is named but not offered as an option: six times as an AI search surface whose visibility Writesonic, Surfer or Frase tracks, once as a point of comparison, once as the model inside another product and once only in an offer to compare tools later. The other general assistants trail: Claude is picked in 28 answers (ChatGPT is picked too in 24 of them), Microsoft Copilot in 7, Gemini in 4, Perplexity in 3. Both ChatGPT-versus-Claude questions pick both: one pairs ChatGPT with a versatile working partner and Claude with prose-first writing, the other says "I'd lean ChatGPT overall" for a novel and suggests testing both on your own voice. Asked for alternatives to ChatGPT, both answers put Claude first.
Specialists win the named uses
In all 15 questions that name a use or a platform, a specialist or the platform's own assistant is picked, and ChatGPT is picked beside it in 9. Sudowrite and Novelcrafter are picked in all four fiction and novel questions, ChatGPT in three of them. Shopify Magic is picked in all three product description and ecommerce questions. Surfer is picked in both SEO content questions: one answer picks it alone ("Surfer SEO is my pick"), the other pairs ChatGPT or Claude for drafting with Surfer or Frase for optimization. Lavender (with ChatGPT) is the pick for cold email, Grantable (with ChatGPT) for grant writing, QuillBot, Wordtune and Grammarly for paraphrasing, and Grammarly, ProWritingAid, LanguageTool and QuillBot for the grammar checker question. Microsoft Copilot is picked for Microsoft 365, and Gemini for Google Workspace, where ChatGPT appears only in an offer to compare tools later. Asked which tool is safest for confidential company documents, the answer picks Microsoft Copilot alone.
Almost every answer reaches a verdict
Every answer recommends at least one dictionary brand, and 96 of 100 pick one. The four without a pick give each option a fit and stop there: two three-way head-to-heads (Jasper versus Copy.ai versus Writesonic; ChatGPT versus Claude versus Gemini) and the alternatives questions for Writesonic and Sudowrite. Twenty-seven of 30 head-to-heads pick every brand named, each for a different case. The one that picks a side is Claude versus Gemini: Claude is "the one I'd test first", and Gemini is described as attractive for research-heavy writing but not picked. Being described is not always being picked: ChatGPT is recommended in 8 answers that do not pick it, Jasper and Grammarly in 7 each, and Gemini, recommended in 11, is picked in 4.
The widest reading list in the series
Across 100 answers there were 304 citation events to 143 domains, more distinct domains than in any earlier teardown. Vendors' own sites took 145 of them, 48 percent. Other third-party pages took 148, 49 percent, the highest share so far, and review-and-media sites 11. jasper.ai is the most-cited domain, in 25 answers, 18 of them to questions that never mention Jasper; grammarly.com is cited in 22 (15 not mentioning Grammarly) and openai.com in 14. The most-cited third party is dupple.com, in 12 answers across five roundup pages, and it ranked in Google's top ten for none of those 12 questions. Reddit ranks in Google's top ten for 93 of the 100 questions and is cited in none; Reddit and Wikipedia have zero citations, as in every teardown so far.
Of the 285 picked brand mentions, 240 went to brands whose own website did not rank in Google's top ten for the question, 84 percent. Google's top ten is 89 percent third-party pages. Forty-one of the 304 citation events involved a domain that also sat in Google's top ten for that query, 13 percent, level with SEO tools for the lowest overlap in the series.
0321 categories, side by side
Same rulebook, every category so far.
| Measure (codebook v2.0) | Project management, Sept 8 | CRM, Sept 17 | Email marketing, Sept 17 | Help desk, Sept 17 | Accounting, Sept 17 | Payment processing, Sept 17 | Payroll, Sept 21 | HR software, Sept 26 | Applicant tracking, Sept 26 | Password managers, Sept 26 | Endpoint security, Sept 26 | Business intelligence, Sept 26 | Data warehouse and ETL, Sept 26 | Ecommerce platforms, Sept 26 | Website builders, Sept 26 | Scheduling, Sept 26 | Video conferencing, Sept 26 | E-signature, Sept 26 | Marketing automation, Sept 26 | SEO tools, Sept 26 | AI writing, Sept 26 |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Recommendations per category answer (average) | 5.9 | 4.3 | 5.0 | 5.5 | 4.3 | 4.2 | 4.6 | 5.0 | 4.5 | 3.4 | 4.7 | 5.0 | 4.5 | 4.3 | 4.3 | 3.4 | 4.0 | 4.6 | 4.4 | 4.3 | 4.1 |
| Answers with no recommended dictionary brand | 1 of 100 | 5 of 100 | 1 of 100 | 1 of 100 | 0 of 100 | 5 of 100 | 1 of 100 | 6 of 100 | 5 of 100 | 3 of 100 | 3 of 100 | 3 of 100 | 2 of 100 | 3 of 100 | 0 of 100 | 5 of 100 | 1 of 100 | 6 of 100 | 4 of 100 | 4 of 100 | 0 of 100 |
| Answers with no pick (the answer's own verdict) | 2 of 100 | 11 of 100 | 2 of 100 | 4 of 100 | 9 of 100 | 22 of 100 | 19 of 100 | 17 of 100 | 12 of 100 | 7 of 100 | 7 of 100 | 5 of 100 | 3 of 100 | 7 of 100 | 2 of 100 | 8 of 100 | 8 of 100 | 11 of 100 | 9 of 100 | 6 of 100 | 4 of 100 |
| Most-recommended brand: appears / recommended | Asana 73 / 73 | HubSpot 75 / 74 | Mailchimp 58 / 56 | Zendesk 70 / 69 | QuickBooks 75 / 73 | Stripe 70 / 68 | Gusto 73 / 73 | Rippling 58 / 57 | Workable 53 / 52 | Bitwarden 84 / 82 | Microsoft Defender 68 / 67 | Power BI 75 / 73 | Snowflake 50 / 50 | Shopify 75 / 75 | Wix 70 / 70 | Calendly 57 / 56 | Zoom 76 / 73 | DocuSign 67 / 65 | HubSpot 64 / 63 | Ahrefs 60 / 59 | ChatGPT 58 / 58 |
| Most-picked brand: appears / picked | Asana 73 / 70 | HubSpot 75 / 69 | Mailchimp 58 / 44 | Zendesk 70 / 61 | QuickBooks 75 / 65 | Stripe 70 / 54 | Gusto 73 / 61 | Rippling 58 / 50 | Workable 53 / 47 | Bitwarden 84 / 78 | Microsoft Defender 68 / 62 | Power BI 75 / 69 | Snowflake 50 / 46 | Shopify 75 / 69 | Wix 70 / 62 | Calendly 57 / 51 | Zoom 76 / 63 | DocuSign 67 / 62 | HubSpot 64 / 57 | Ahrefs 60 / 55 | ChatGPT 58 / 50 |
| Head-to-head queries recommending every named brand | 30 of 30 | 28 of 30 | 30 of 30 | 29 of 30 | 26 of 30 | 28 of 30 | 30 of 30 | 28 of 30 | 29 of 30 | 28 of 30 | 30 of 30 | 29 of 30 | 28 of 30 | 28 of 30 | 30 of 30 | 29 of 30 | 30 of 30 | 26 of 30 | 30 of 30 | 29 of 30 | 30 of 30 |
| Head-to-head queries picking every named brand | 30 of 30 | 23 of 30 | 29 of 30 | 29 of 30 | 25 of 30 | 19 of 30 | 21 of 30 | 21 of 30 | 29 of 30 | 27 of 30 | 29 of 30 | 29 of 30 | 28 of 30 | 27 of 30 | 29 of 30 | 29 of 30 | 26 of 30 | 25 of 30 | 30 of 30 | 29 of 30 | 27 of 30 |
| Recommendation-intent queries with a dictionary recommendation | 19 of 20 | 18 of 20 | 20 of 20 | 20 of 20 | 20 of 20 | 19 of 20 | 20 of 20 | 18 of 20 | 20 of 20 | 19 of 20 | 19 of 20 | 20 of 20 | 20 of 20 | 19 of 20 | 20 of 20 | 19 of 20 | 19 of 20 | 20 of 20 | 19 of 20 | 20 of 20 | 20 of 20 |
| Recommendation-intent queries with a pick | 19 of 20 | 18 of 20 | 20 of 20 | 20 of 20 | 19 of 20 | 18 of 20 | 20 of 20 | 18 of 20 | 20 of 20 | 19 of 20 | 19 of 20 | 20 of 20 | 20 of 20 | 19 of 20 | 20 of 20 | 19 of 20 | 19 of 20 | 20 of 20 | 18 of 20 | 20 of 20 | 20 of 20 |
| Recommended mentions where the brand does not rank in Google's top 10 | 398 of 468 (85%) | 269 of 387 (70%) | 313 of 419 (75%) | 350 of 445 (79%) | 206 of 368 (56%) | 294 of 360 (82%) | 202 of 383 (53%) | 310 of 405 (77%) | 333 of 388 (86%) | 218 of 304 (72%) | 273 of 369 (74%) | 355 of 401 (89%) | 360 of 426 (85%) | 313 of 376 (83%) | 324 of 376 (86%) | 241 of 325 (74%) | 298 of 349 (85%) | 282 of 368 (77%) | 302 of 352 (86%) | 314 of 366 (86%) | 315 of 362 (87%) |
| Picked mentions where the brand does not rank in Google's top 10 | 349 of 416 (84%) | 226 of 330 (68%) | 270 of 370 (73%) | 291 of 380 (77%) | 141 of 279 (51%) | 170 of 222 (77%) | 113 of 246 (46%) | 232 of 311 (75%) | 261 of 311 (84%) | 163 of 241 (68%) | 231 of 319 (72%) | 292 of 336 (87%) | 303 of 365 (83%) | 227 of 285 (80%) | 262 of 309 (85%) | 200 of 276 (72%) | 227 of 271 (84%) | 229 of 308 (74%) | 259 of 306 (85%) | 258 of 309 (83%) | 240 of 285 (84%) |
| Google top 10 that is third-party pages | 746 of 1,000 (75%) | 710 of 1,000 (71%) | 720 of 1,000 (72%) | 714 of 1,000 (71%) | 743 of 1,000 (74%) | 787 of 1,000 (79%) | 653 of 1,000 (65%) | 820 of 1,000 (82%) | 871 of 1,000 (87%) | 866 of 1,000 (87%) | 778 of 1,000 (78%) | 823 of 999 (82%) | 777 of 1,000 (78%) | 868 of 1,000 (87%) | 906 of 1,000 (91%) | 780 of 999 (78%) | 873 of 1,000 (87%) | 697 of 1,000 (70%) | 862 of 1,000 (86%) | 879 of 1,000 (88%) | 891 of 1,000 (89%) |
| Citation events to vendors' own sites | 216 of 362 (60%) | 136 of 320 (42%) | 193 of 367 (53%) | 152 of 345 (44%) | 125 of 302 (41%) | 161 of 301 (53%) | 192 of 314 (61%) | 167 of 325 (51%) | 139 of 311 (45%) | 201 of 292 (69%) | 149 of 266 (56%) | 190 of 274 (69%) | 197 of 267 (74%) | 194 of 277 (70%) | 189 of 331 (57%) | 137 of 296 (46%) | 170 of 280 (61%) | 191 of 302 (63%) | 190 of 301 (63%) | 170 of 306 (56%) | 145 of 304 (48%) |
| Answers citing only vendor pages | 50 of 100 | 40 of 100 | 37 of 100 | 27 of 100 | 34 of 100 | 47 of 100 | 49 of 100 | 34 of 100 | 30 of 100 | 65 of 100 | 44 of 100 | 60 of 100 | 60 of 100 | 55 of 100 | 41 of 100 | 42 of 100 | 52 of 100 | 44 of 100 | 47 of 100 | 49 of 100 | 47 of 100 |
| Share of citations in the 10 most-cited domains | 54% | 40% | 42% | 45% | 55% | 58% | 55% | 46% | 44% | 72% | 58% | 62% | 60% | 61% | 54% | 35% | 54% | 57% | 53% | 42% | 38% |
| Citation events whose domain is in Google's top 10 | 83 of 362 (23%) | 83 of 320 (26%) | 97 of 367 (26%) | 80 of 345 (23%) | 99 of 302 (33%) | 98 of 301 (33%) | 134 of 314 (43%) | 85 of 325 (26%) | 59 of 311 (19%) | 78 of 292 (27%) | 72 of 266 (27%) | 44 of 274 (16%) | 54 of 267 (20%) | 56 of 277 (20%) | 51 of 331 (15%) | 63 of 296 (21%) | 43 of 280 (15%) | 73 of 302 (24%) | 56 of 301 (19%) | 41 of 306 (13%) | 41 of 304 (13%) |
| Reddit and Wikipedia citations | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 | 0 |
All columns are coded under codebook v2.0 by two independent AI readers per answer; the project management column is the September 8 dataset recoded under it. Each teardown is one run per query in its own window, so differences between columns mix category with collection date.
04What this changes
Four things, in order.
Name the job you do better than a general assistant. In all 15 questions that name a use or a platform, a specialist or the platform's own assistant was picked. On the seven category questions that name no use, ChatGPT was picked in all seven. A specialist's pages should say plainly which job it is for.
Your own site is read for other people's questions. jasper.ai was cited in 18 answers to questions that do not mention Jasper, grammarly.com in 15. Use-case, pricing and comparison pages are material the model reaches for.
Roundup sites are part of your footprint. dupple.com was cited in 12 answers without ranking for any of them. If a roundup library covers your category, check whether you are in it and what it says.
Being described is not being picked. Gemini is recommended for a stated case in 11 answers and picked in 4. A fit label in a list of options is visibility, not a verdict.
05Limitations
What this teardown cannot tell you.
One run per query means answer variance is unmeasured; Benchmark 01 runs each query three times across three surfaces. The teardowns are collected on different days, so differences between categories mix the category with the date. The brand dictionary covers the general AI writing tools market and deliberately excludes vertical tools, so their appearances are described in prose and not counted. The readers are AI models, not people: they follow a written protocol and agree with each other closely, but a shared blind spot would not show up as disagreement. The line between picked and recommended is a judgment, documented in the protocol with examples. Sentiment is not coded. No vendor-tool cross-check was read for this category. Google's control counts a brand as ranking only when its own domain is in the top ten; a listicle that features the brand does not count. One run per question, one day, United States, English, logged out. Answers vary between runs, so these are frequencies for this sample. The main limitation is structural: ChatGPT is judging a category that includes ChatGPT, and a single surface cannot separate the category's shape from a preference for its own product; that needs the same questions asked of other assistants. The ChatGPT row also counts OpenAI and GPT model names. The codes come from AI readers, not people; the two readers agreed on 97.3 percent of codes, and the calls settled by a third reader are listed in coder-notes.md. The line between picked and recommended is a judgment, and a different protocol would move some counts. Writer is matched in the dictionary only by its domain and model name; the readers added it where they saw it named, and some mentions may still be missed.
06Dataset
Check it, don't believe it.
Every number above can be recomputed from these files. CC BY 4.0: use them, cite the page.
- queries.csv: the 100 queries with intent labels.
- brands.csv: the 53-brand dictionary with aliases and canonical domains.
- mentions.csv: 414 coded brand mentions with position, type, a 0/1 picked column and whether the brand's domain was in Google's top ten.
- citations.csv: 304 citation events with domain class and Google overlap.
- observations.csv: one row per query with brand, recommendation, citation and control counts.
- dictionary-changes.md: a ChatGPT alias change tried after collection and reverted; the dictionary used is the one fixed before collection
- coder-notes.md: coding method, reader agreement, the calls settled by a third reader, and dictionary notes
- codebook.md: the rulebook, with dated amendments through v2.0.
- reader-protocol.md: the written protocol both readers coded against (codebook v2.0).
- picked_stats.json: the picked-level figures.
The earlier teardowns: Teardown 01, project management, Teardown 02, crm, Teardown 03, email marketing, Teardown 04, help desk, Teardown 05, accounting, Teardown 06, payment processing, Teardown 07, payroll, Teardown 08, hr software, Teardown 09, applicant tracking, Teardown 10, password managers, Teardown 11, endpoint security, Teardown 12, business intelligence, Teardown 13, data warehouse and etl, Teardown 14, ecommerce platforms, Teardown 15, website builders, Teardown 16, scheduling, Teardown 17, video conferencing, Teardown 18, e-signature, Teardown 19, marketing automation, Teardown 20, seo tools.
Twenty-one categories, and the planned twenty are done.
AI writing tools is the last of the twenty categories planned for the series; payment processing was an extra. Here the model's picks track vendor pages and a set of roundup sites that do not rank. In password managers, 69 percent of citations went to the vendors' own websites. Finding out what the model is reading for your category is the first thing a Category Salience Brief does, with a query set you approve first.